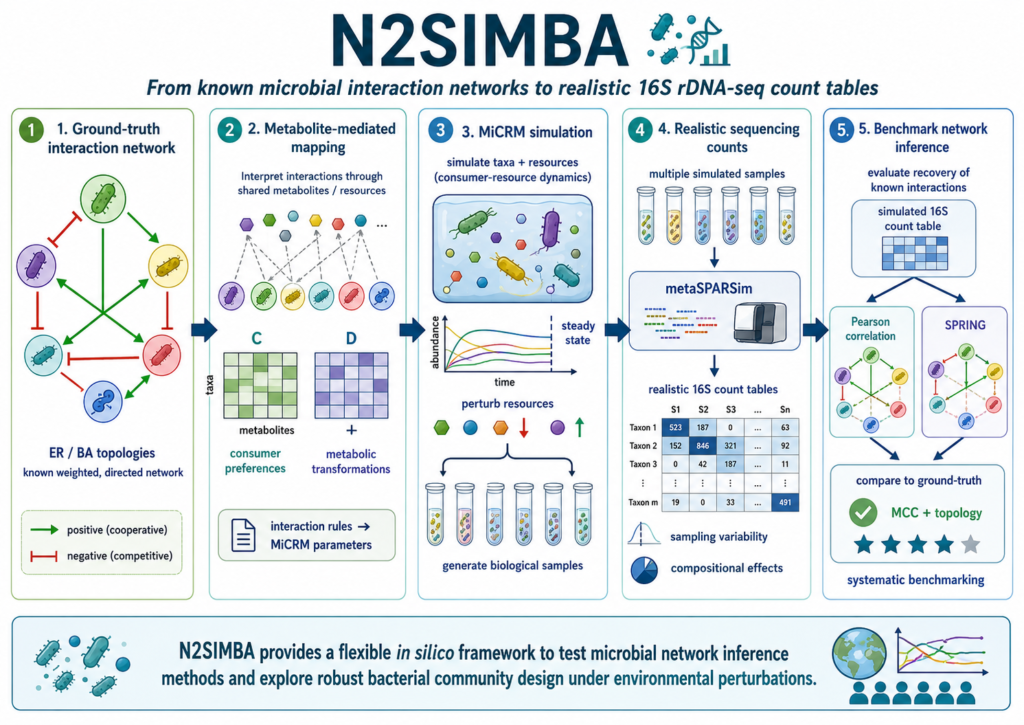

How accurately can we reconstruct microbial interactions from microbiome sequencing data? In our recently published study in PLOS Computational Biology, we address this question through a comprehensive benchmark of 18 computational methods for inferring microbial co-occurrence networks.
Since reliable experimental ground truth for microbial interactions is difficult to obtain, we used synthetic 16S rDNA-seq datasets generated with known underlying interaction networks. Using the N2SIMBA simulator, we designed 189 different simulation scenarios, resulting in a total of 9,450 datasets. These scenarios covered a broad range of experimental and ecological conditions, including different numbers of samples and microbial species, sequencing depths, community diversity levels, network structures, and proportions of competitive interactions.
We evaluated the methods from several perspectives, assessing their ability to identify individual interactions, recover the centrality of key species, reconstruct the overall network topology, and their computational requirements.
Our results reveal important limitations in the current co-occurrence-based approach. Although some methods perform well under favourable conditions, their accuracy decreases considerably in more challenging and realistic scenarios. In particular, performance is strongly influenced by the number of samples relative to the number of species, network density, sequencing depth, and the prevalence of competitive interactions. Overall, conditional-dependence methods showed the most consistent performance, with SPRING achieving the best overall results, followed by CCLasso and COZINE.
Our findings highlight the importance of carefully evaluating and interpreting microbial networks inferred from sequencing data. While co-occurrence analysis remains a valuable tool for generating ecological hypotheses, recovering the true interaction structure of a microbial community is a much more challenging task than simple statistical association. Further methodological and computational developments are needed to improve the reliability of microbial interaction inference.
Congratulations to Piero Mariotto, Matteo Baldan, Barbara Di Camillo and Giacomo Baruzzo for this work!
The article, together with the benchmark datasets, results, and software resources, is openly available:
Read the article: PLOS Computational Biology
Explore the data and computational resources: Zenodo repository
Access the source code: GitLab repository
This work was made possible by the support of the European Union – NextGenerationEU, and of our partner company, EuBiome S.r.l.